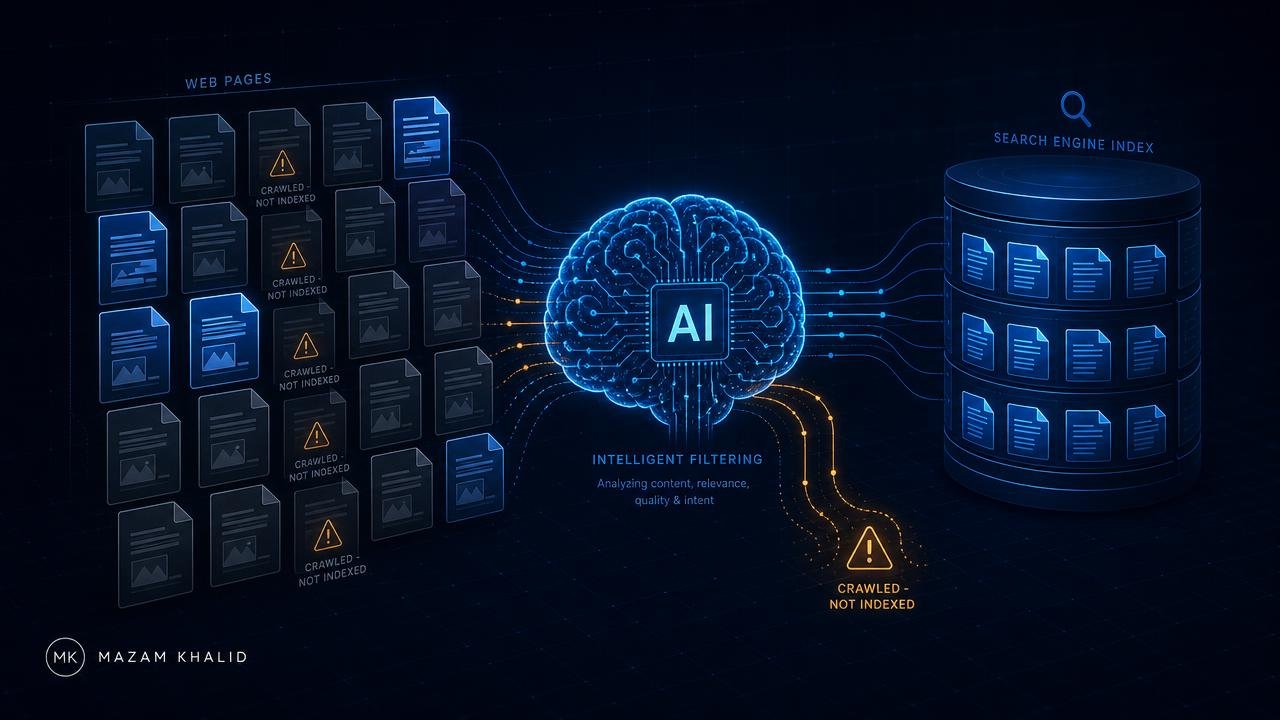
Across the sites I audit, one Search Console state has grown faster than everything else combined: Crawled – currently not indexed. The page returns 200, it's in the sitemap, it's internally linked, Googlebot fetched it — and it never enters the index. This is not a bug. It is the visible edge of a change in how search engines decide what is worth storing.
Key takeaways
- Crawling is cheap; indexing is expensive. Selection has tightened, not discovery.
- The bar is marginal value: does this page add anything not already in the index?
- AI-scaled publishing raised the volume of near-duplicate pages, which raised the bar for everyone.
- Fixes are architectural — consolidation, rendering, crawl efficiency, entity clarity — not "request indexing" again.
What actually changed
Three things happened at once, and they compound.
1. Publishing volume exploded. Generative tools made it trivial to produce competent, unremarkable pages at scale. The web now contains vastly more text saying roughly the same thing. An index has finite value per unit of storage and serving cost; when supply of near-identical documents multiplies, the marginal value of admitting one more collapses.
2. Selection moved earlier in the pipeline. Historically a page could be indexed and then buried at position 80. Increasingly that page is simply not admitted. From the outside this looks like an indexing bug; internally it's a cost decision made before ranking ever happens.
3. Retrieval changed shape. AI overviews and assistant answers pull passages from a smaller set of trusted, well-structured documents rather than presenting ten links. Being "in the index somewhere" is worth less than it was; being the canonical, comprehensive source on a topic is worth more.
The question the index is asking about your page
Not "is this good?" — that's unmeasurable at scale. The operative question is closer to: if we admit this document, does a user query exist that it answers better than anything we already hold?
Reframing your unindexed pages around that question is uncomfortable and useful. A 1,400-word article titled "What Is Technical SEO?" is not bad. It is redundant. There is no query for which it is the best available answer. That is why it sits unindexed while a 600-word page documenting a specific error message and its fix gets indexed within a day.
The seven causes I actually find
1. Intra-site near-duplication
The most common by far. Location pages, service-by-city permutations, product variants and tag archives that differ by a noun. Google crawls twenty, indexes two, and the remaining eighteen consume crawl budget forever. If your pages differ only by find-and-replace, they will be treated as one page.
2. Thin clusters with no hub
Ten disconnected 800-word articles on adjacent topics compete with each other and corroborate nothing. One 2,500-word pillar with ten genuinely distinct spokes, reciprocally linked, indexes far more reliably. Topical structure is an indexing signal, not just a ranking one.
3. Render-dependent content
If the meaningful content only exists after JavaScript executes, indexing depends on the render queue — which is deprioritised for low-authority sites. A page whose raw HTML is an empty <div id="root"> may be crawled repeatedly and never indexed. Details in JavaScript SEO for React and SPAs.
4. Crawl budget spent on garbage
Faceted URLs, session parameters, calendar archives, filter combinations. When 70% of bot requests hit URLs that will never be indexed, the pages you care about are visited less often and re-evaluated less often. Log analysis is the only way to see this honestly.
5. Slow, unstable responses to bots
Sustained TTFB above ~600ms for Googlebot, or intermittent 5xx under crawl load, throttles crawl rate directly. Shared hosting with no object cache is the usual culprit; so, increasingly, is unthrottled AI crawler traffic hammering the same origin.
6. Contradictory canonical and directive signals
Sitemap says index, canonical points elsewhere, hreflang references a URL that 301s, pagination canonicalises to page one. Each contradiction is a reason to defer a decision. Deferral looks exactly like "Crawled – currently not indexed".
7. Weak entity footprint
A new domain with no consistent identity signals — no connected Person/Organization graph, no corroborating profiles, no author with a verifiable track record — starts with a low trust prior. The same content on an established domain indexes immediately. This is unfair and it is how it works.
Do AI crawlers hurt indexing?
GPTBot, ClaudeBot, PerplexityBot, Google-Extended and CCBot are separate from Googlebot's index pipeline. They do not decide your Google indexing. But on a modest VPS, AI crawler volume can be a third of total bot traffic, and the consequence is measurable: higher origin TTFB, more 429/5xx responses, and reduced Googlebot crawl rate.
The correct response is rate limiting at the edge, not blanket blocking:
- Cloudflare rate-limit rules per AI user agent (e.g. 60 requests/minute), not a firewall block.
- Full-page caching so bot requests are served from cache, never from PHP.
Crawl-delayin robots.txt for the bots that honour it.- Keep AI bots allowed if you want assistant citations — see GEO vs SEO vs AEO for what that visibility is worth.
The fix sequence that works
- Inventory. Export every URL in each Search Console coverage state. Group by template, not by URL. Patterns live at template level.
- Consolidate. For each group of near-duplicates, choose one URL to be definitive, merge the substance into it, 301 the rest. Expect to remove 30–60% of URLs on a bloated site.
- Deepen what remains. Add what only you can add: measurements, configuration, error output, before/after numbers, dated observations. Specificity is the differentiator a model or a ranking system can verify.
- Fix rendering. Ensure primary content, canonical, title and meta exist in the initial HTML response.
- Reclaim crawl budget. Block or noindex parameter and facet space, remove infinite calendar paths, flatten redirect chains, prune the sitemap to canonical 200-status URLs only.
- Make responses fast and stable. Object cache, page cache, tuned PHP-FPM, CDN, and rate limits on non-search bots. Target sub-300ms TTFB for bot requests.
- Strengthen the entity graph. Connected JSON-LD with stable
@idreferences across Person, Organization, WebSite and page types; consistent NAP and profile links off-site. - Re-submit and monitor. Only after something material changed. Then watch the state transitions daily — automate it with the n8n indexing regression monitor.
Realistic timelines
| Action | Typical first movement |
|---|---|
| Fix contradictory canonicals | 3–10 days |
| Server-render previously client-only content | 1–3 weeks |
| Consolidate near-duplicate templates | 3–8 weeks |
| Substantially deepen thin pages | 4–10 weeks |
| Build entity trust on a new domain | 3–6 months |
The uncomfortable conclusion
The AI effect on indexing is not that search engines dislike AI content. It's that AI made competent-but-redundant content free to produce, and the index responded by raising the price of admission. The sites that recover are the ones that publish fewer pages with more in them — pages carrying information that did not exist anywhere else before they were written.
If you're staring at thousands of unindexed URLs, start with the Search Console indexing triage guide, then work the consolidation sequence above.